TL;DR.
Triple differences can relax parallel trends by borrowing information from an auxiliary domain. We give identification formulas and doubly robust semiparametric estimators for both panel and repeated cross-section data. The repeated cross-section setup also allows covariates to change over time.
Why this matters.
It puts triple-difference analysis on a modern semiparametric footing, with flexible nuisance estimation and robustness guarantees. It also avoids the usual no-compositional-change assumption for repeated cross-sections.
Abstract
The triple difference causal inference framework is an extension of the well-known difference-in-differences framework. It relaxes the parallel trends assumption of the difference-in-differences framework through leveraging data from an auxiliary domain. Despite being commonly applied in empirical research, the triple difference framework has received relatively limited attention in the statistics literature. Specifically, investigating the intricacies of identification and the design of robust and efficient estimators for this framework has remained largely unexplored. This work aims to address these gaps in the literature. From the identification standpoint, we present outcome regression and weighting methods to identify the average treatment effect on the treated in both panel data and repeated cross-section settings. For the latter, we relax the commonly made assumption of time-invariant composition of units. From the estimation perspective, we develop semiparametric estimators for the triple difference framework in both panel data and repeated cross-sections settings. These estimators are based on the cross-fitting technique, and flexible machine learning tools can be used to estimate the nuisance components. We characterize conditions under which our proposed estimators are efficient, doubly robust, root-n consistent and asymptotically normal. As an application of our proposed methodology, we examined the effect of mandated maternity benefits on the hourly wages of women of childbearing age and found that these mandates result in a 2.6% drop in hourly wages.
The paper at a glance
An informal guide to the problem, the idea, and the main results.
1. The problem
Triple-difference designs use an auxiliary comparison dimension to relax the parallel-trends burden of ordinary difference-in-differences. But the classical formulas do not directly give a modern semiparametric treatment, especially once we want flexible nuisance estimation and repeated-cross-section data.
2. The key idea
We write the target causal parameters in a form that makes the identifying structure explicit, and then derive influence-function-based estimators. That yields doubly robust procedures: we can combine outcome and propensity-type models, and consistency survives if one side is estimated well enough.
3. Identification
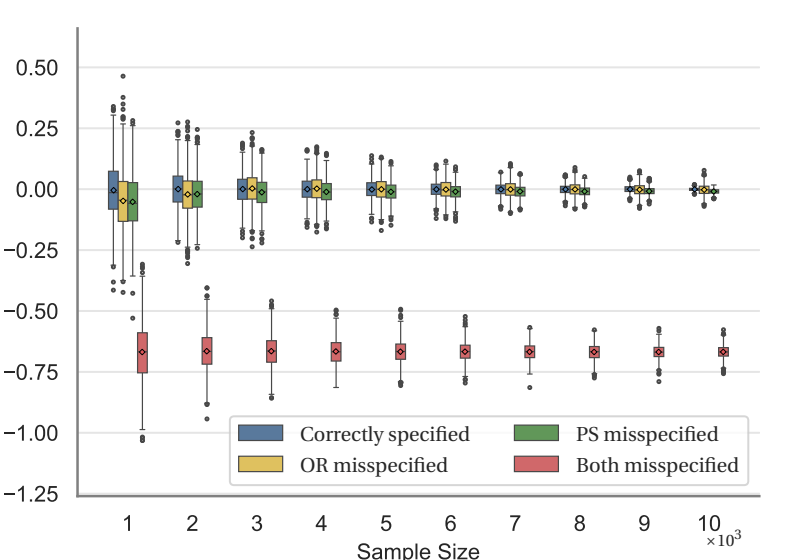
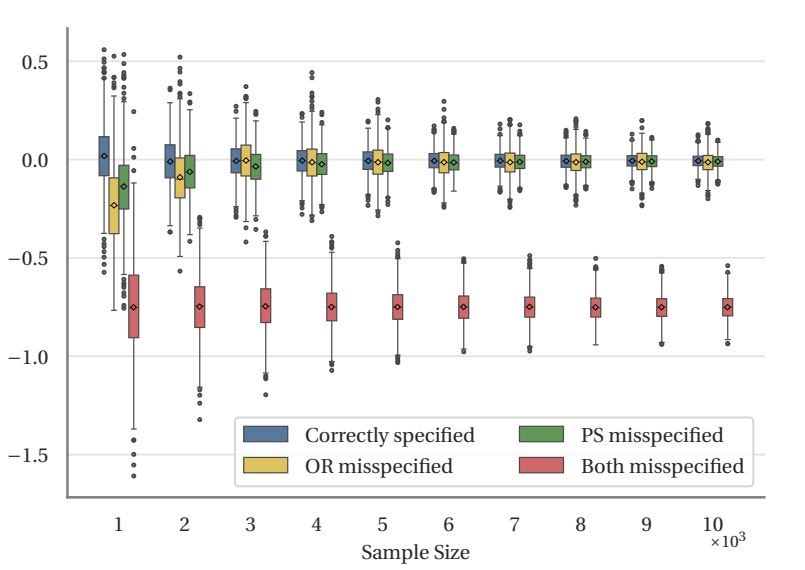
We give both outcome-regression and weighting identification formulas for the ATT in panel data and repeated cross-sections. In the repeated cross-section setting, identification does not require the usual time-invariant composition of sampled units.
4. Semiparametric guarantees
We derive cross-fitted influence-function estimators and characterize conditions under which they are efficient, doubly robust, root-n consistent, and asymptotically normal while allowing flexible machine-learning estimation of nuisance functions.
5. How it works
- Define the target triple-difference estimands clearly for panel and repeated-cross-section settings.
- Express the estimands in a form that supports efficient influence-function calculations.
- Build doubly robust estimators using nuisance functions that can be fit flexibly.
- Use the resulting scores for inference and for robustness against nuisance-model misspecification.
What the simulations and application show
Where this helps
Good fit
- You want a modern semiparametric version of triple differences.
- You work with panel data or repeated cross-sections and want one coherent framework.
- You want doubly robust estimation with machine-learning-friendly nuisance fitting.
- You care about policy evaluation when a third comparison dimension is scientifically meaningful.
Keep in mind
- The framework covers both panel data and repeated cross-sections, with identification and semiparametric estimation tailored to each sampling design.
- For repeated cross-sections, the method explicitly accommodates compositional changes over time rather than requiring a time-invariant sampled population.
Cite this paper
@misc{akbari2025semiparametric,
  title        = {Semiparametric Triple Difference Estimators},
  author       = {Sina Akbari and Negar Kiyavash and AmirEmad Ghassami},
  year         = {2025},
  eprint       = {2502.19788},
  archivePrefix= {arXiv},
  primaryClass = {econ.EM},
  url          = {https://arxiv.org/abs/2502.19788}
}